Video presentation 11:22
The motivation, protocol, and findings behind the Telephone Game.
ECCV 2026
How much meaning survives when a model turns text into images, and back again?
Institute of Artificial Intelligence, University of Central Florida, USA
* Corresponding author · † Equal second authors · ‡ Equal third authors
01 / The evaluation gap
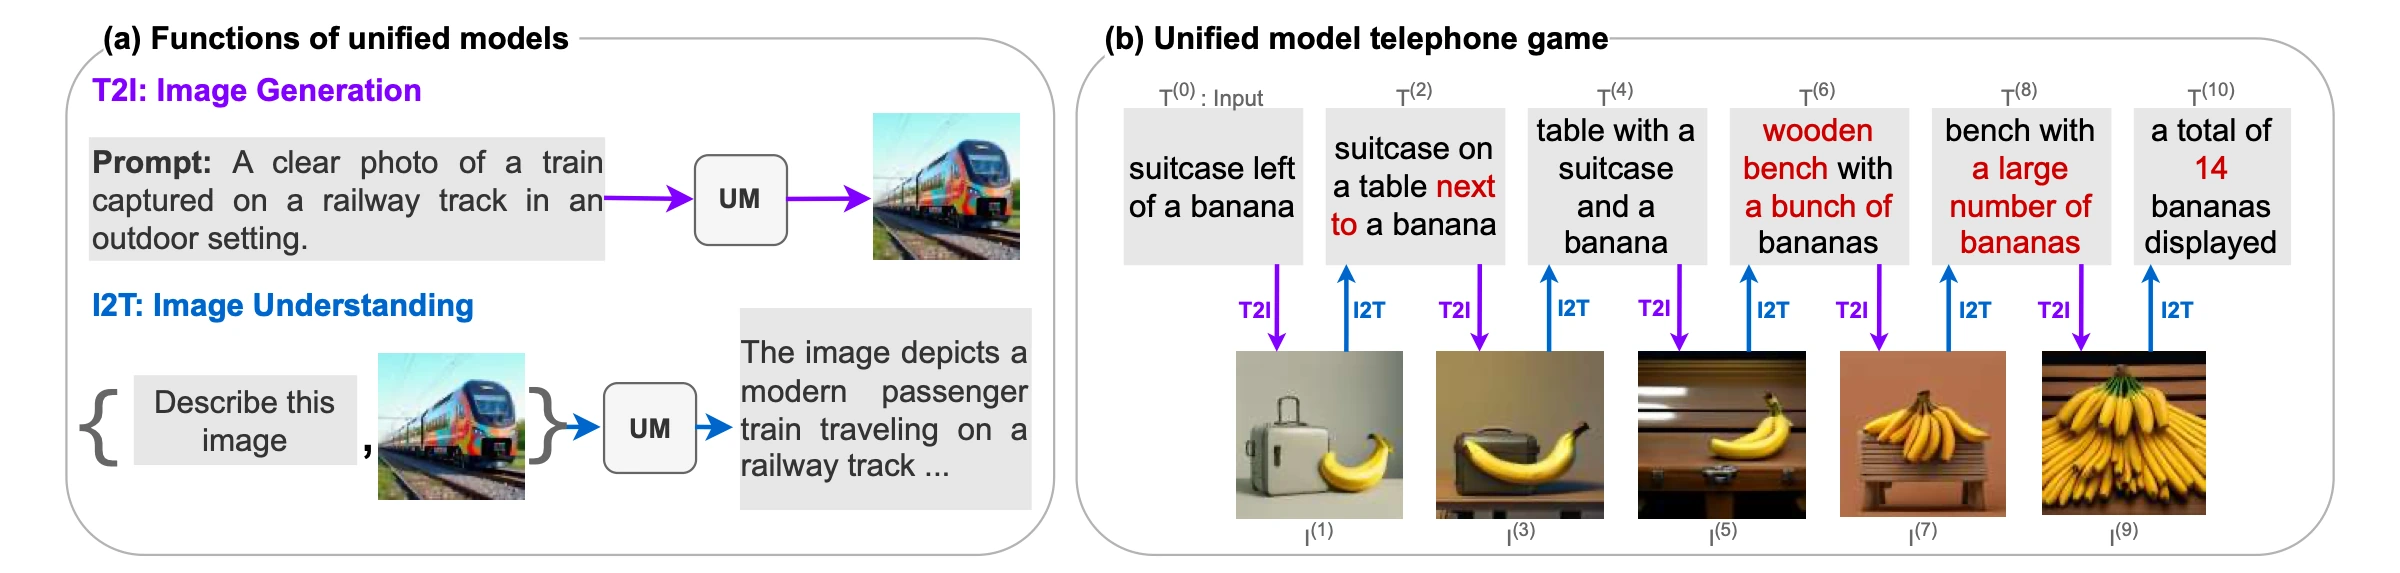
Unified models can both describe images and generate them. Standard benchmarks test these abilities separately; our telephone game tests what happens when a model repeatedly uses them together.

The gap in one example
BAGEL correctly identifies a winning chess position, yet generates a generic board when asked to depict the same concept. This mismatch is cross-inconsistency.
Watch & explore
The motivation, protocol, and findings behind the Telephone Game.
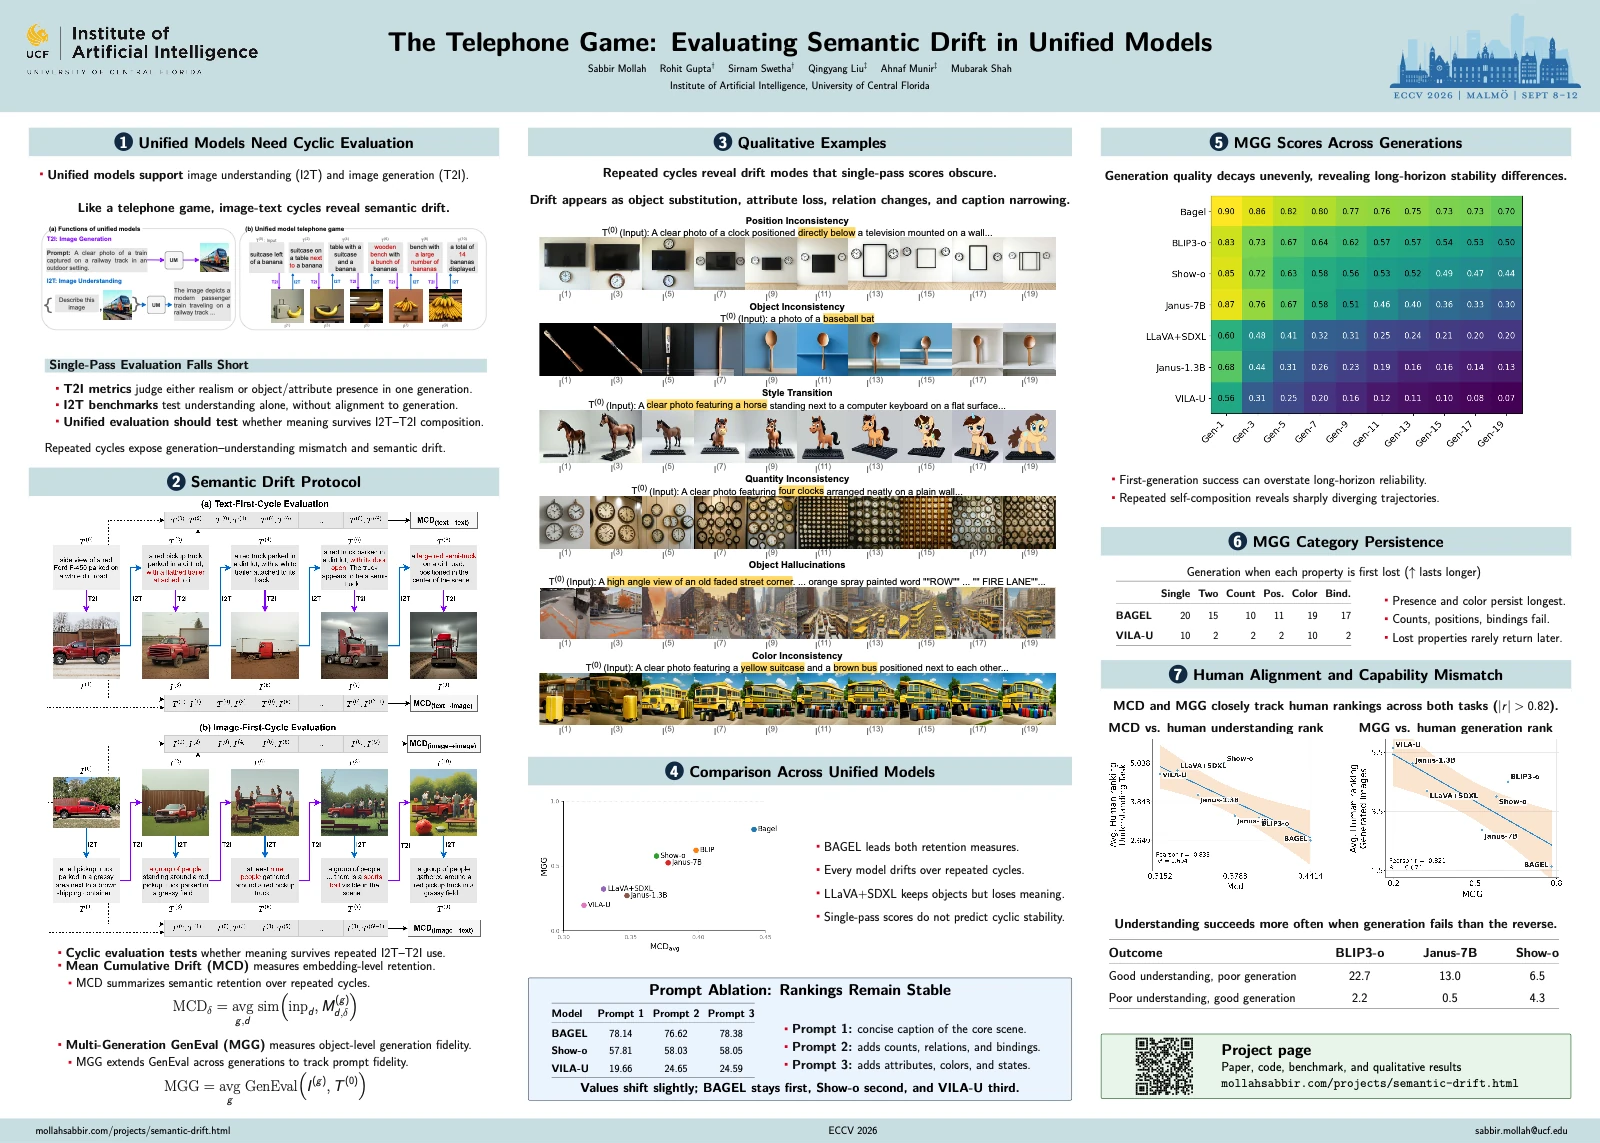
A visual overview of the work.
02 / The protocol
The Semantic Drift Protocol (SDP) starts with a caption or an image, then alternates text-to-image (T2I) and image-to-text (I2T). Each output becomes the next input; fidelity is always measured against the original.
TextImageText
Does the original description survive?
ImageTextImage
Does the original scene survive?
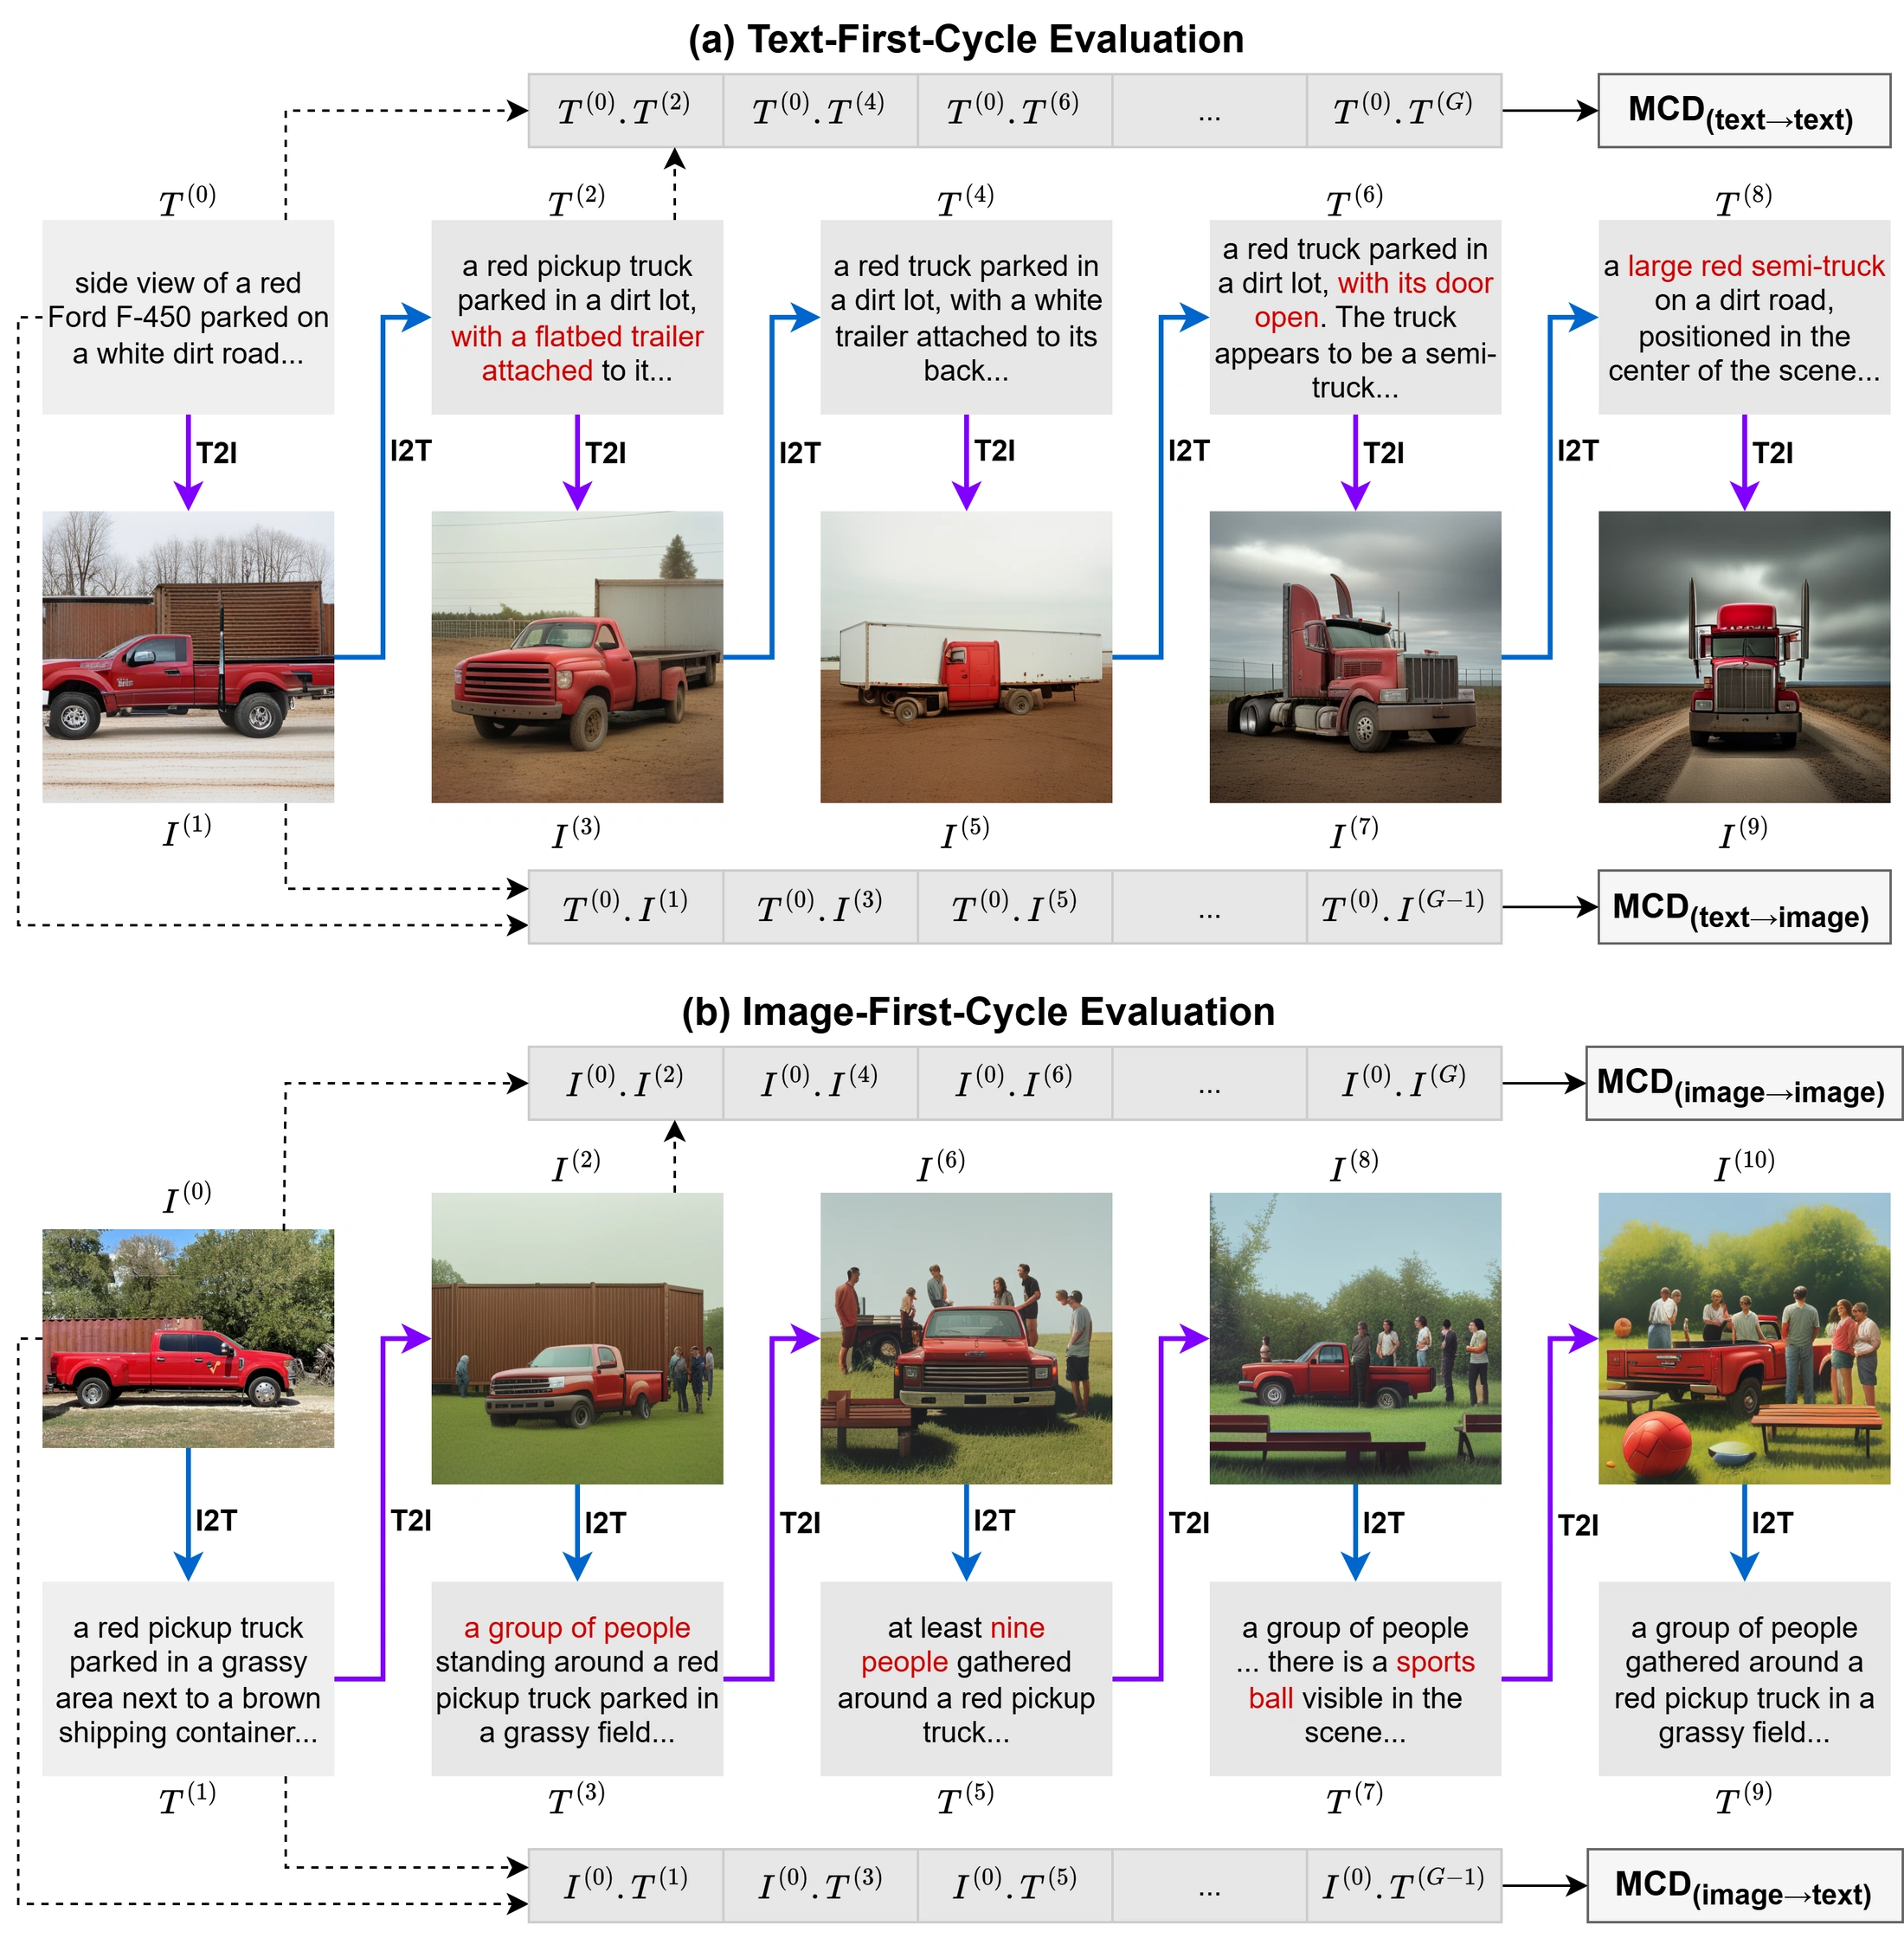
Embedding similarity captures the scene’s overall meaning; object-level evaluation checks its specific constraints.
MCD ↑ Higher is better
Average semantic similarity across generations and four modality mappings.
Despite the name, a higher MCD score means stronger retention and less drift.
MGG ↑ Higher is better
Object-level prompt compliance across repeated generations, using rewritten GenEval prompts and OWLv2 detections.
Measures whether a model preserves structured scene details over time.
03 / Qualitative examples
Repeated generation can change an object’s identity, position, count, color, or style—and introduce content that was never in the prompt. These six examples show semantic drift unfolding across the chain.
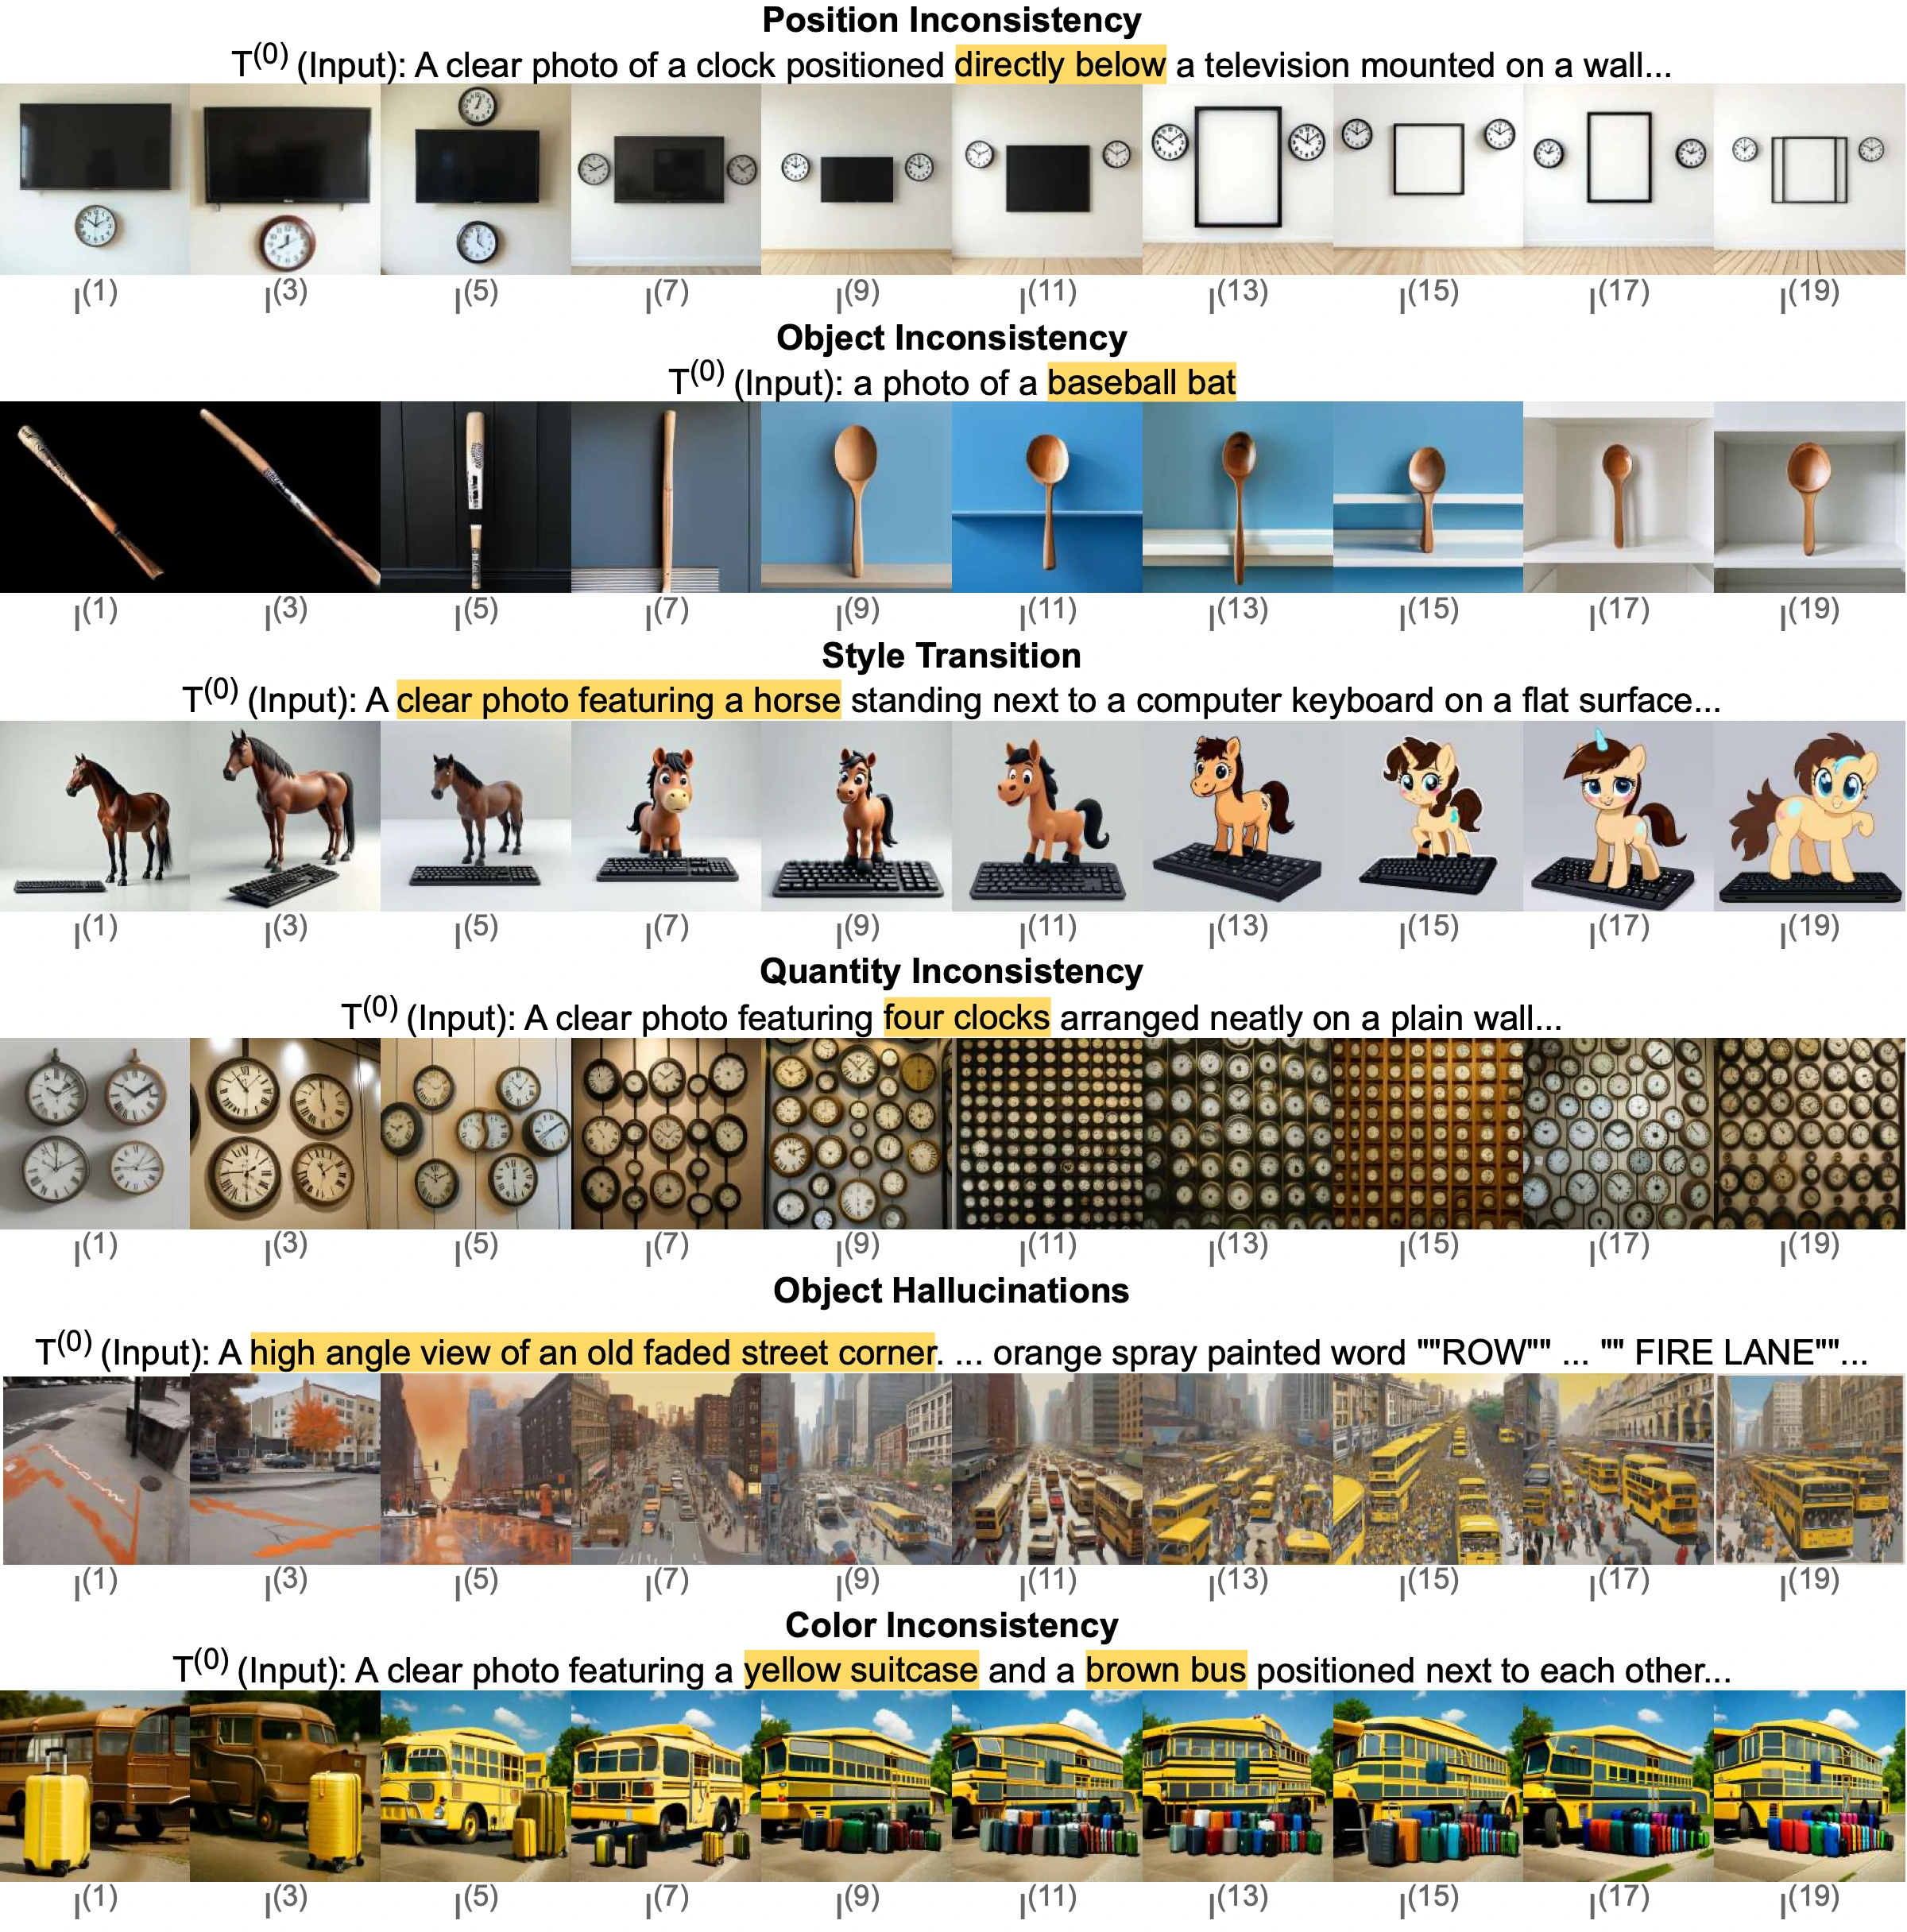
The clock’s position is lost.
A baseball bat becomes a spoon.
A photograph becomes a cartoon.
Four clocks become an unspecified set.
A city appears around an empty road.
A brown bus turns yellow.
04 / Comparison across models
BAGEL leads both retention measures across the seven systems. LLaVA+SDXL illustrates why both metrics matter: preserving individual objects does not guarantee that the scene’s overall meaning survives.
| Model | MCDavg ↑ | MGG ↑ |
|---|---|---|
| BAGEL Best | 0.4414 | 78.2 |
| BLIP3-o | 0.3984 | 62.2 |
| Show-o | 0.3691 | 57.8 |
| Janus-7B | 0.3778 | 52.5 |
| LLaVA+SDXL | 0.3298 | 32.3 |
| Janus-1.3B | 0.3470 | 27.0 |
| VILA-U | 0.2829 | 19.7 |
Higher is better for both metrics. Rows follow the paper’s MGG ordering; MCD rankings differ.
05 / Across generations
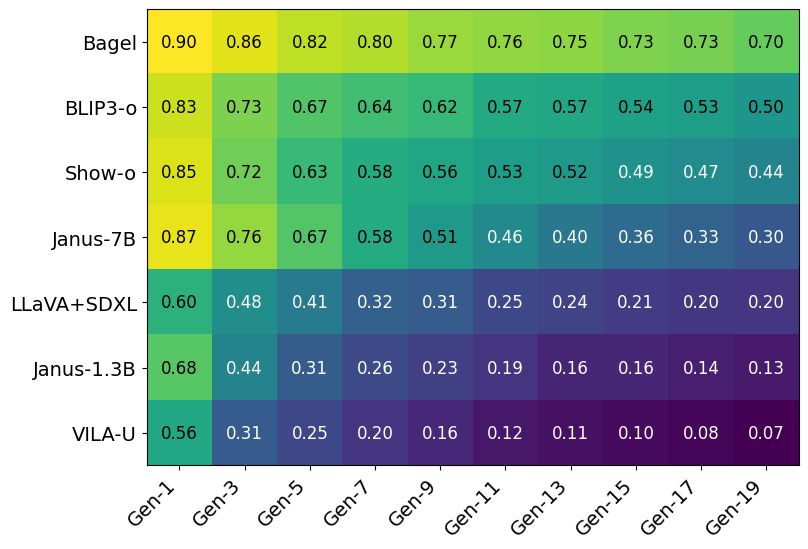
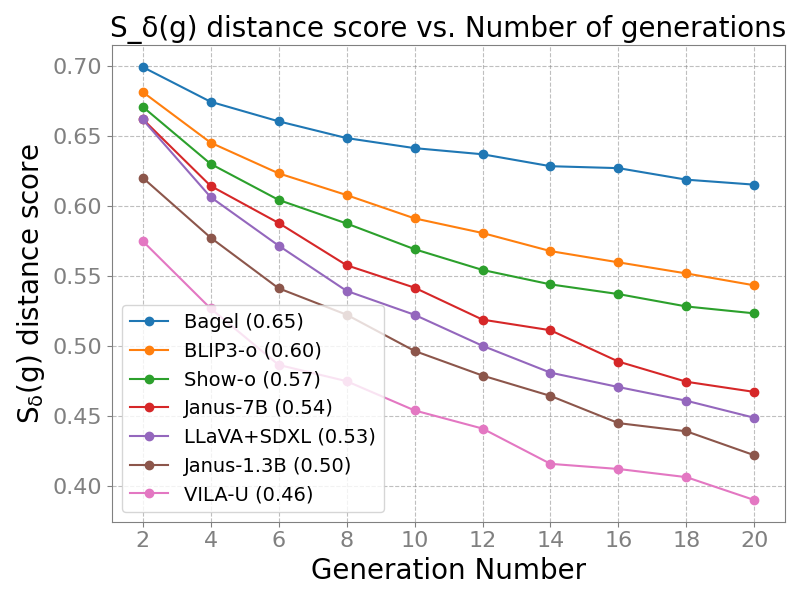
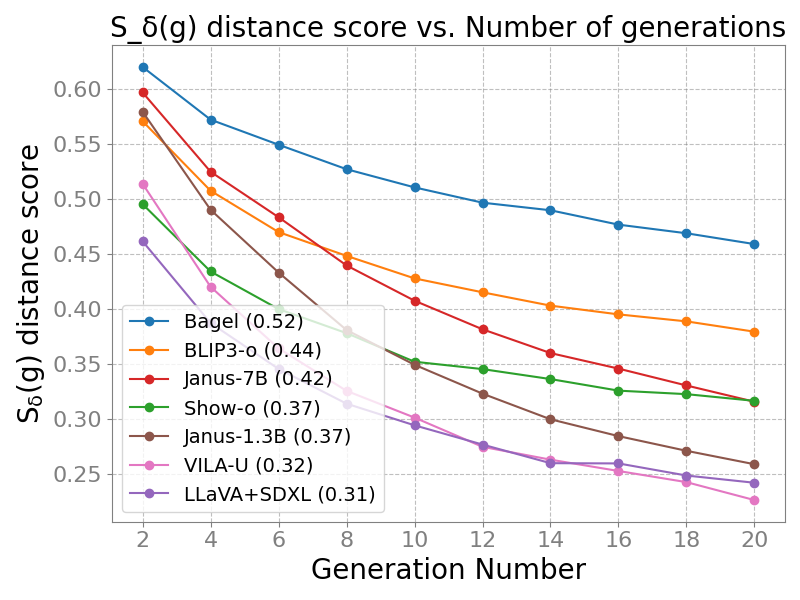
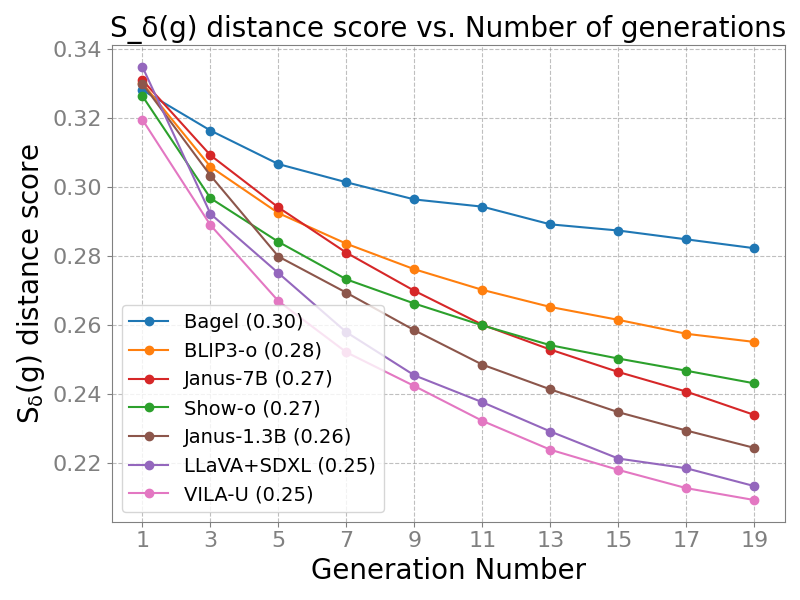
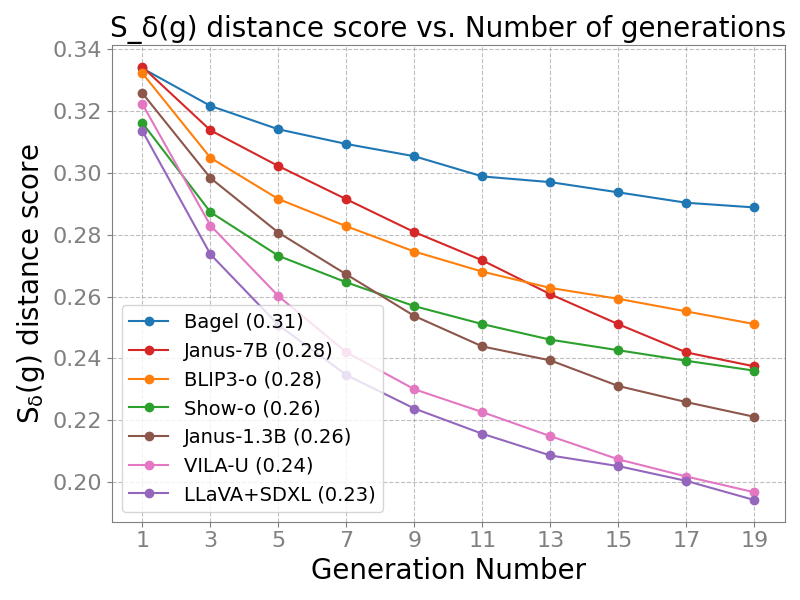
Similar initial scores diverge as models repeatedly use their own outputs. BAGEL remains comparatively stable, while weaker models lose their connection to the original scene.
06 / What fails first
Simple object presence and color persist longer. Counts, spatial relations, and attribute bindings tend to fail earlier.
| Model | Single object | Two objects | Count | Position | Color | Binding |
|---|---|---|---|---|---|---|
| BAGEL | 20 | 15 | 10 | 11 | 19 | 17 |
| VILA-U | 10 | 2 | 2 | 2 | 10 | 2 |
Two representative systems from the poster’s category-persistence comparison.
A critical mistake changes the input for every later step. Subsequent generations compound the error, making semantic collapse difficult to recover from.
07 / Human evaluation
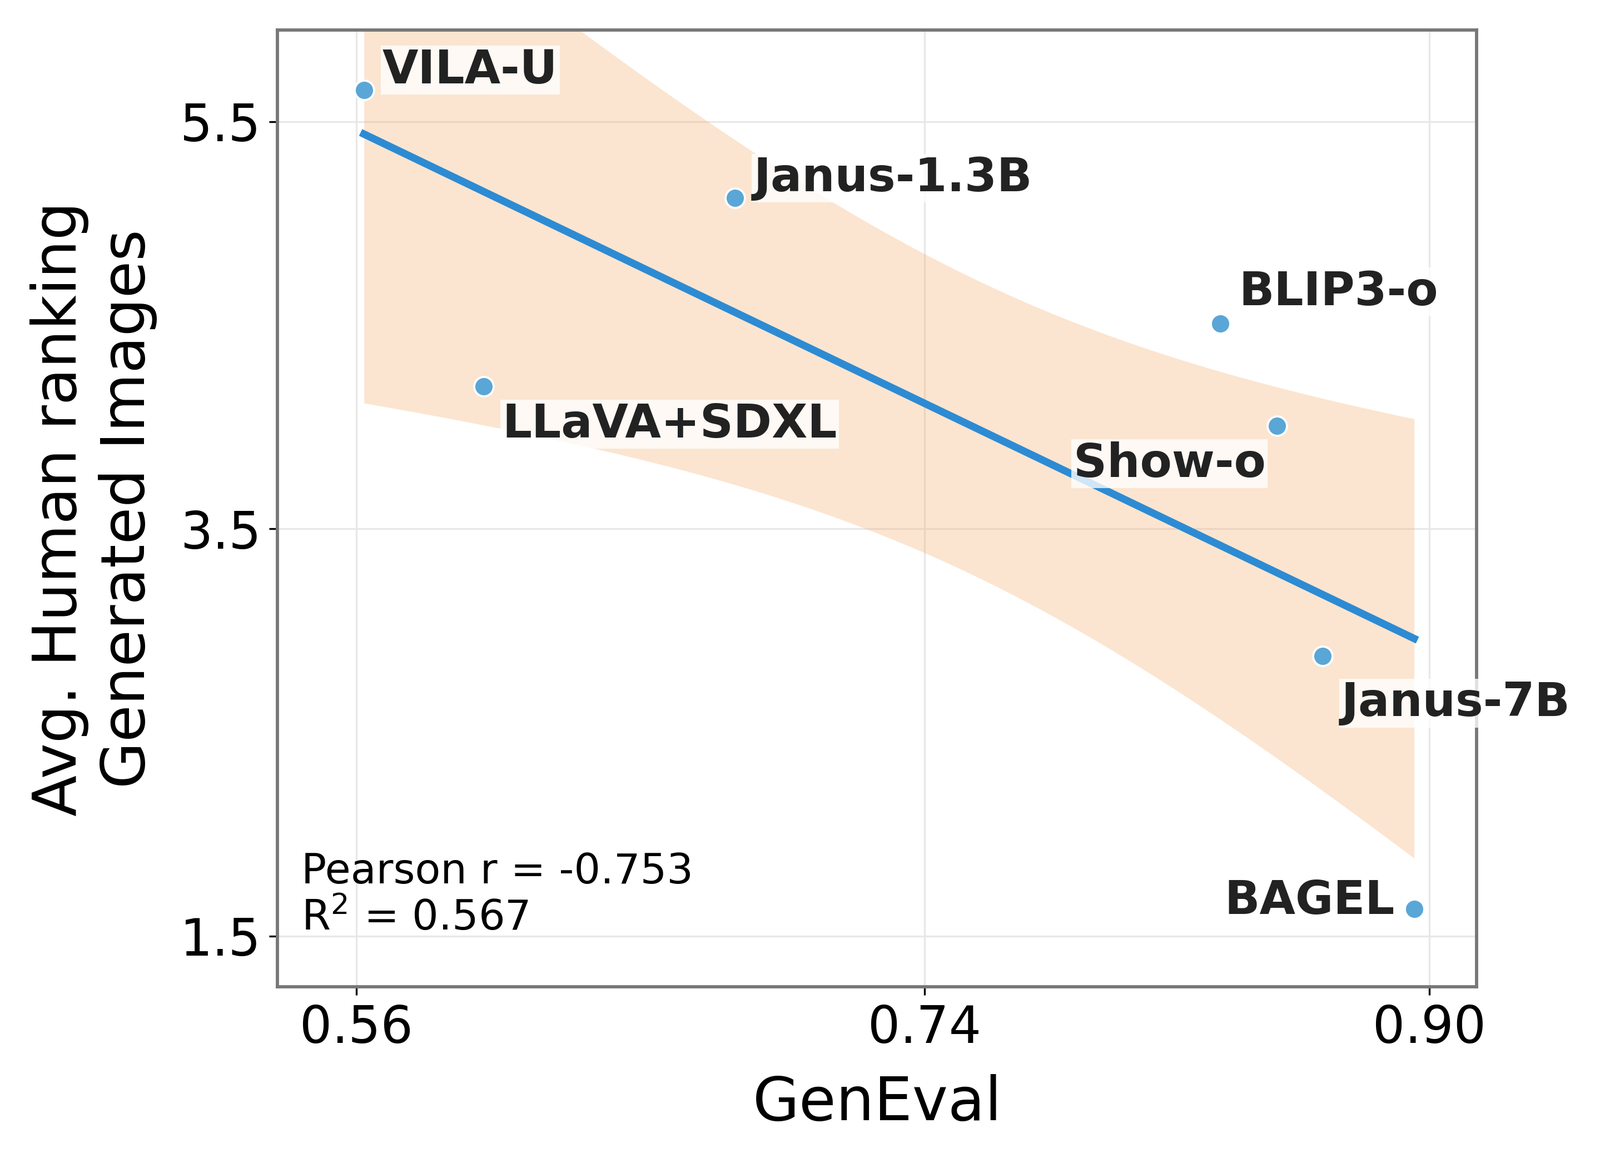
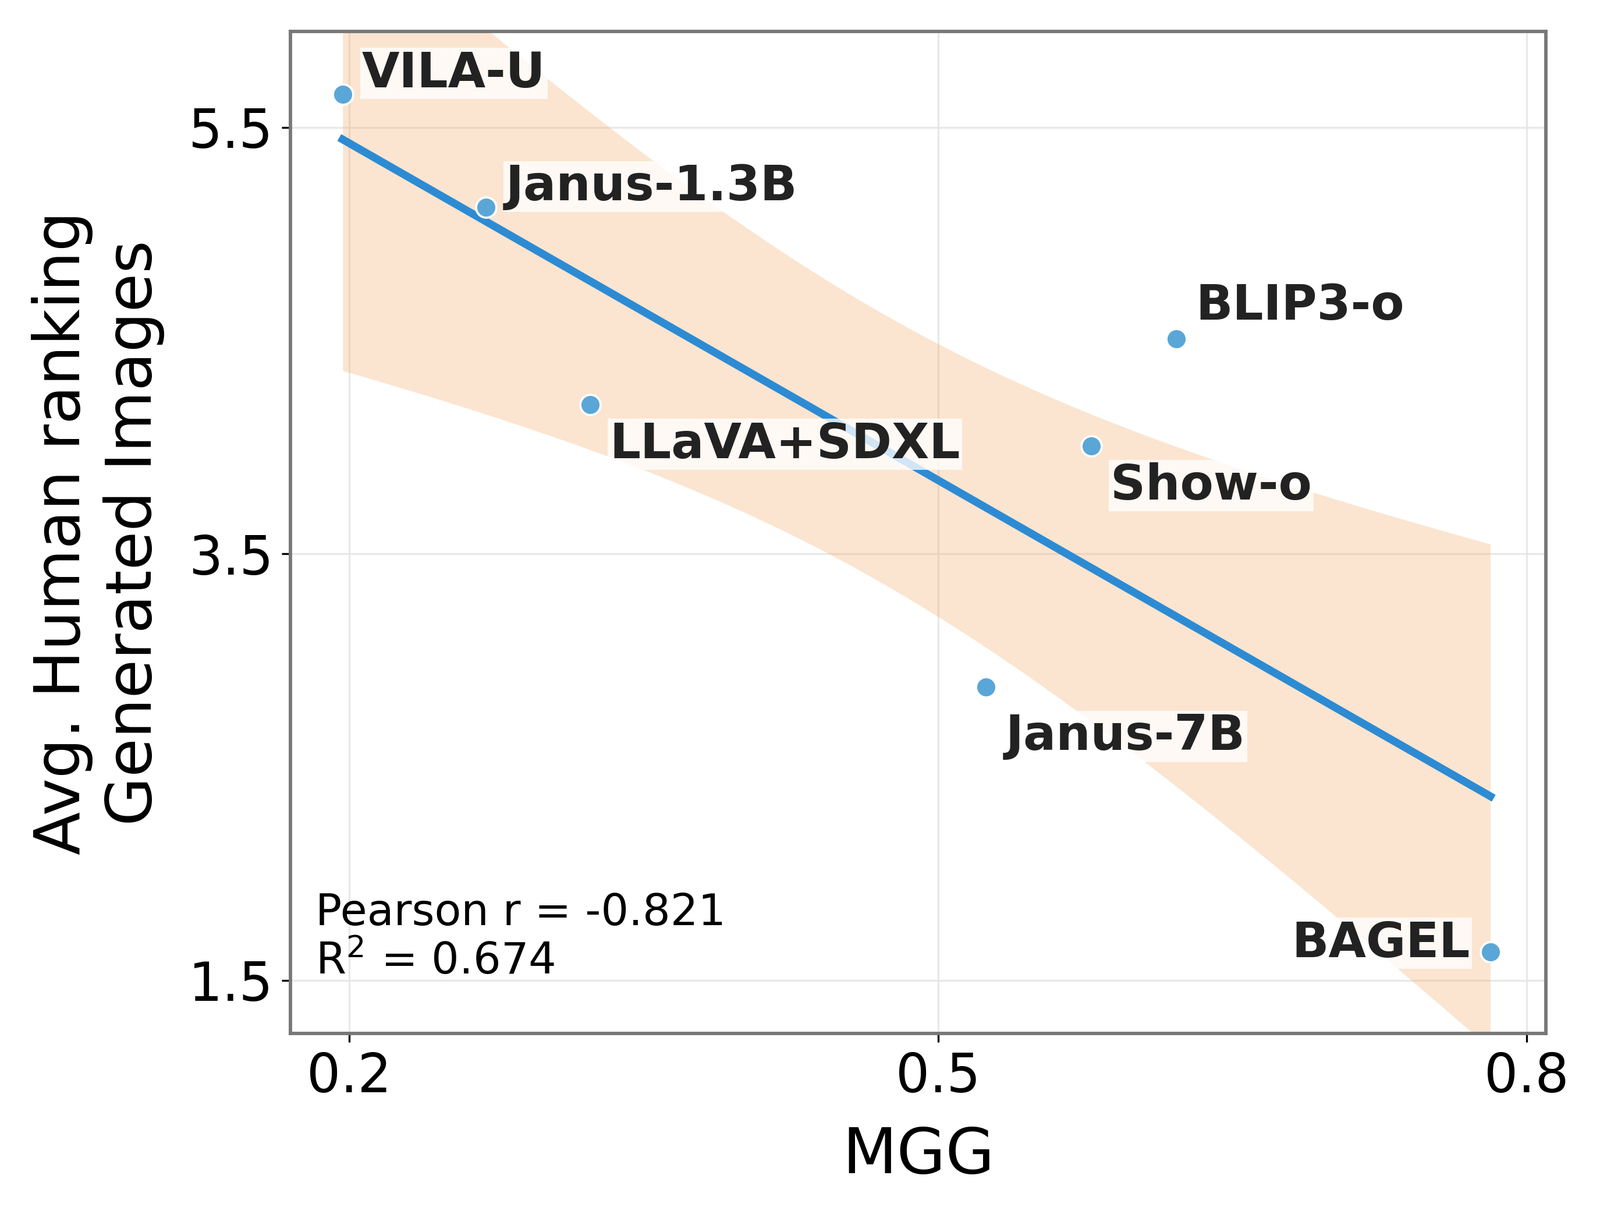
Six annotators assessed understanding and generation on 200 examples, with two independent annotations per example. Model identities were hidden and output order randomized. MCD and MGG strongly agree with their rankings.
Strong agreement with human judgments.
Closer agreement than single-pass GenEval.
The single-pass comparison.
Pearson correlations across the seven systems. Negative values reflect that lower human rank is better, while higher metric scores are better.
The human study reveals the same mismatch that motivates cyclic evaluation: a model can understand an input well but fail to generate it faithfully.
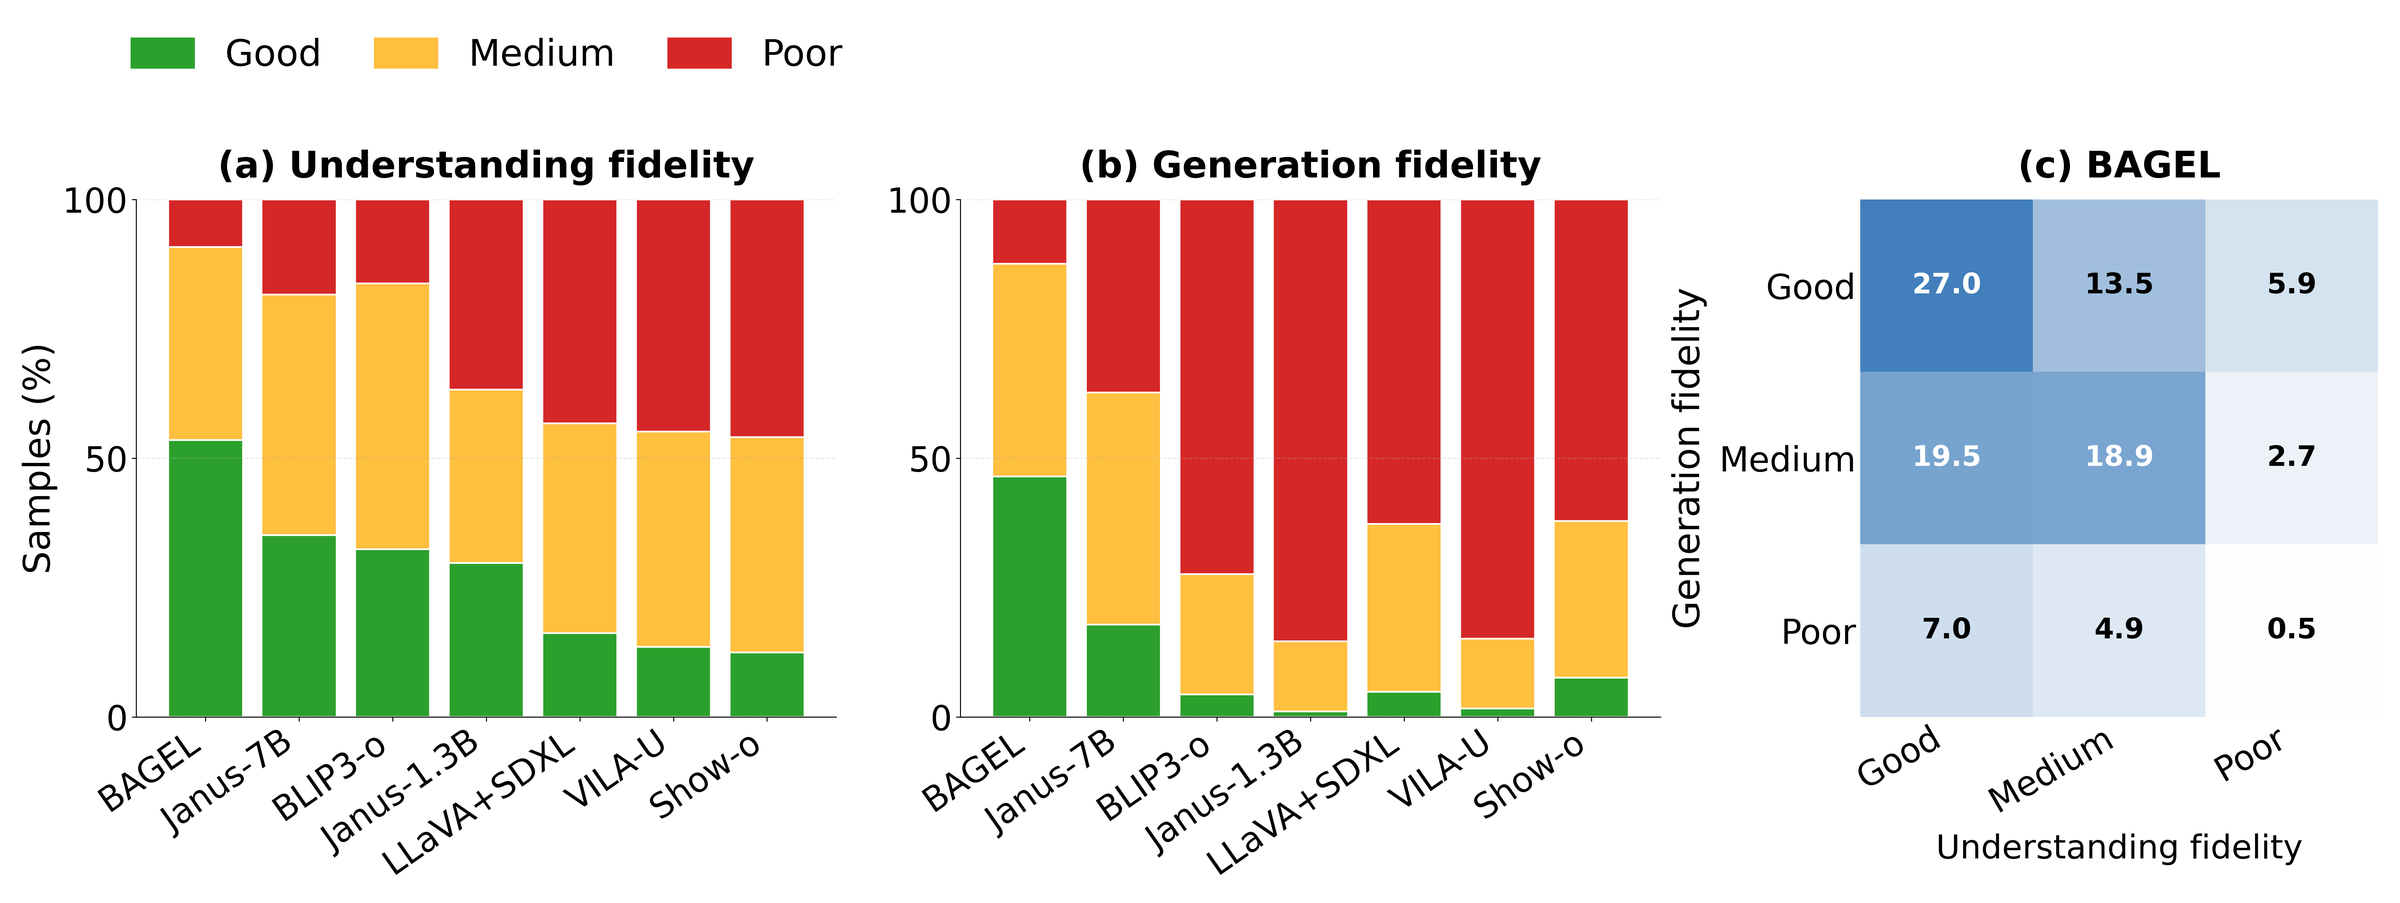
| Model | Good understanding, poor generation | Poor understanding, good generation |
|---|---|---|
| BLIP3-o | 22.7% | 2.2% |
| Janus-7B | 13.0% | 0.5% |
| Show-o | 6.5% | 4.3% |
Use this work
Accepted at ECCV 2026. The BibTeX below references the arXiv preprint.
@misc{mollah2025telephonegameevaluatingsemantic,
  title={The Telephone Game: Evaluating Semantic Drift in Unified Models},
  author={Sabbir Mollah and Rohit Gupta and Sirnam Swetha and
          Qingyang Liu and Ahnaf Munir and Mubarak Shah},
  year={2025},
  eprint={2509.04438},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2509.04438}
}